Fine-tuning produces artifacts that need to be understood before deployment. With LoRA, the output is generally an adapter associated with a base model, not a replacement full checkpoint that can always be loaded by itself.
Keep one release together
LLaMA-Factory’s official quickstart supplies training, inference, and export configurations. Check out a release tag and use the examples and dependency instructions from that same checkout. Record the resolved commit and GPU/runtime versions with an experiment.
This note explains that workflow rather than claiming that an arbitrary CUDA wheel and a few legacy script flags form a tested training recipe. The project supports multiple model families; a workflow should select one explicitly.
A reproducible release path
For the historical CLI generation, v0.9.1 contains matching Llama 3 train, adapter inference, and merge configurations. The commands below require accepted model access and a compatible GPU environment installed according to that release’s README. They are an upstream workflow reference, not a completed GPU benchmark here.
git clone --branch v0.9.1 --depth 1 https://github.com/hiyouga/LlamaFactory.git
cd LlamaFactory
pip install -e ".[torch,metrics]"
llamafactory-cli train examples/train_lora/llama3_lora_sft.yaml
llamafactory-cli chat examples/inference/llama3_lora_sft.yaml
llamafactory-cli export examples/merge_lora/llama3_lora_sft.yaml
Review overwrite_output_dir before running training in a directory with results you want to keep. The merge configuration uses the base model plus the adapter path and warns against quantized merging; do not add an arbitrary quantization_bit to it. The example model is an 8B checkpoint, so check the memory budget before starting.
Register data before training
An instruction dataset needs a schema and a registered name. For example, an illustrative record can contain an instruction, optional input, and expected output. The corresponding dataset registration maps those columns to the format expected by the selected training stage. Merely passing a JSON filename to an unrelated CLI flag does not establish that mapping.
Use a train/validation split that avoids near-duplicate examples across boundaries. A tiny two-record dataset is suitable for checking plumbing, not for claiming model improvement.
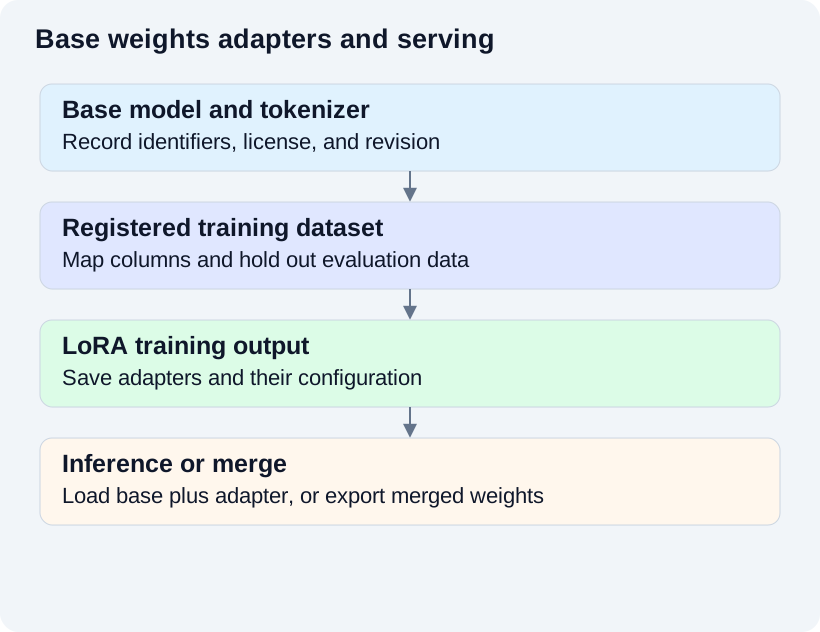
Conceptual illustration; labels describe responsibilities, not a deployment specification.
Train chat and export
The current documented CLI family is llamafactory-cli train, llamafactory-cli chat, and llamafactory-cli export, each supplied with a configuration file. Use the paths supplied by the release’s examples rather than inventing a legacy train_bash.py or export_model.py invocation. Project usage.
The configuration must agree on the base model, prompt template, adapter path, and tokenizer. For inference, either load the base plus its adapter through a supported path, or merge/export as instructed by that release. Preserve the original adapter so another merge can be reproduced.
Quantization and resource planning
Quantized training, adapter training, checkpoint conversion, and an inference engine’s supported weight format are separate choices. A quantization option in one stage does not prove every export path is supported.
Before a GPU run, estimate memory for weights, optimizer state, activations, sequence length, and batch size; measure the actual peak. Use the model’s documented requirements and a small dry run. This workflow was not GPU-benchmarked as part of the editorial revision.
After experimentation, stop rented compute and remove only the temporary checkpoints you no longer need. Evaluate the tuned model on held-out tasks and regressions before calling the export production-ready.