Reading notes from 2023; revised November 17, 2026. Reported architecture and scale refer to the source period.
Every optimization needs an accounting boundary
Erik Peterson’s talk uses expensive engineering mistakes to make cloud cost concrete. The transferable lesson is to connect resource consumption to the code path and workload that causes it.
Work through the mechanism
For an illustrative request-cost example, assume one million jobs each performs 100 redundant object-store reads. That is 100 million reads. Reusing one result per job would reduce that part to one million reads, but only if the cached result remains valid. Multiply the request counts by the applicable region/tier price rather than claiming one universal saving.
A logging example needs the same discipline: events per request × requests × bytes per event gives ingested bytes. Retention and query scans are additional costs. Removing a debug statement can reduce volume, but losing the only useful incident signal can create another operating cost.
Thresholds create discontinuities
An item-size billing boundary can make a small attribute change expensive. State the service’s accounting unit, rounding rules, payload size before/after, and write mode. “Adding a timestamp doubles cost” is not a general rule for every record.
Make efficiency a ratio with a purpose
A proposed (revenue - cloud cost) / revenue measure requires a defined time interval and revenue denominator. It is not a substitute for cost per successful job, tenant, or user action, and it is undefined at zero revenue.
I would pair technical telemetry with ownership tags, budgets, and periodic checks for orphaned resources. Compare total workload cost and user outcomes after a change, not only a smaller bill line.
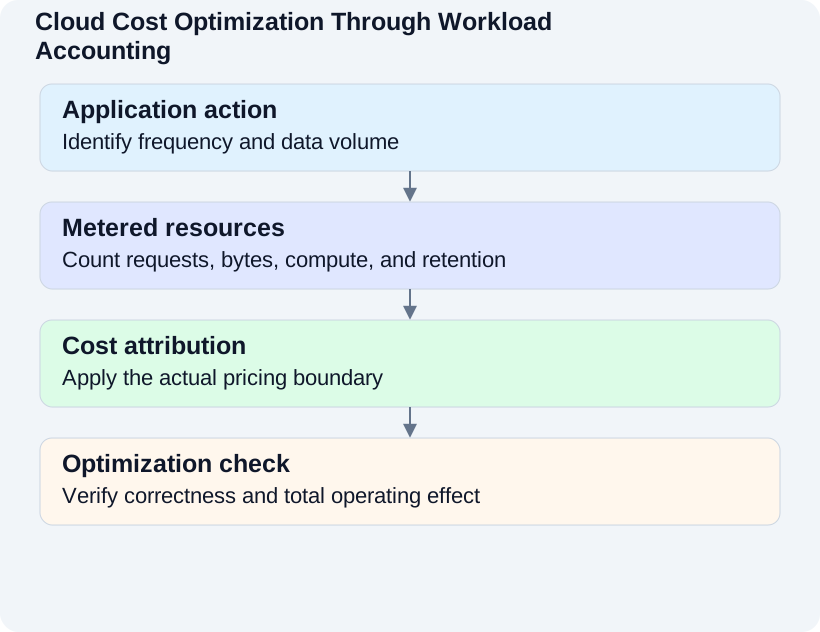
Conceptual illustration; labels describe responsibilities, not a deployment specification.